Last updated: October 28, 2026
Key Takeaways
- The right setup depends on team size, release risk, and coordination needs.
- Fix the smallest bottleneck that removes the most waiting.
- The everyday workflow should stay small, predictable, and hard to misuse.
- The first engineering operations wins come from removing repeated interruptions, not demo-friendly tools.
Developer workflow and engineering operations are the systems that decide whether software ships in hours, days, or weeks. Quick answer: the right setup is usually the one that removes the biggest bottleneck first, and this guide explains how to choose it. If you want fewer broken builds, faster reviews, and less time spent chasing CI failures or release confusion, this guide for Developer workflow and engineering operations — The Complete Guide is for the team that has to deliver work every week, not for abstract org charts.
What Actually Determines the Right Answer Here
The right setup depends on team size, release risk, and how much coordination your work requires. If your team is five engineers pushing one service with low blast radius, the answer is usually a lightweight workflow built around GitHub, code review, and a single CI pipeline. If you are running a regulated product, a monorepo, or a multi-team platform with shared services, the answer shifts toward stricter controls, clearer ownership, and more engineering operations discipline.
Therefore, the trap is treating “better workflow” as one tool purchase. If the situation involves compliance, security, or safety-sensitive systems, consult a qualified professional before changing controls; sources such as the NIST Secure Software Development Framework and Google’s SRE guidance are useful starting points. It is usually a sequence problem. A developer waits on a review, the review waits on a green test run, the test run waits on a stale branch, and the release waits on someone who remembers the manual steps. Engineering operations exists to remove those waits. That means looking at the whole path: issue intake, branch strategy, local dev setup, CI, code review, release, deployment, observability, and incident feedback.
The trade-off is speed versus control. A trunk-based flow with short-lived branches and small pull requests is fast, but it only works if the team keeps the trunk healthy and the tests are dependable. A more gated process with change approvals and release branches can reduce risk, but it slows merges and creates more operational overhead. The wrong choice is often the one copied from a larger or more regulated company with a completely different failure mode.
| Situation | Best Path | Why Other Options Fail |
|---|---|---|
| Small product team shipping frequently | Trunk-based development, GitHub or GitLab PRs, fast CI, feature flags | Heavy release branching adds ceremony without reducing much risk |
| Platform team supporting multiple squads | Clear service ownership, CI templates, standardized alerts, release notes | Ad hoc workflows create inconsistent deployments and unclear on-call handoffs |
| Regulated or customer-facing critical system | Change controls, protected branches, audited approvals, deployment records | Pure “move fast” workflows create compliance gaps and harder incident review |
| Monorepo with many shared libraries | Bazel, Nx, Turborepo, or carefully scoped CI paths | Full-repo builds on every change waste time and mask ownership problems |
If you are deciding from scratch, start with the bottleneck, not the ideology. If the bottleneck is review latency, fix PR size and reviewer routing. If it is flaky CI, fix test stability before adding more checks. If it is deployment fear, add progressive delivery and rollback paths before rewriting the whole workflow. According to GitHub’s own guidance on pull requests and reviews, smaller changes tend to move faster through review.
Quick check: if your team can explain where a change gets stuck in under 30 seconds, you know where to start.
If You’re Starting from a Messy Workflow, What Do You Fix First?
You fix the smallest thing that removes the most waiting, not the loudest complaint. If developers are spending 20 minutes setting up a laptop, 45 minutes waiting on CI, and another day waiting for a review, the order matters: local setup first if onboarding is the worst pain, CI next if every commit is blocked, review flow after that if merges are the bottleneck.
A common mistake is trying to “optimize engineering operations” with a giant platform overhaul. That usually creates a quarter of churn and very little improvement. The better path is to map the actual sequence one developer follows from task assignment to production. Look at the time lost at each handoff. Then remove the biggest single delay before touching the rest.
If you need a practical sequence, use this:
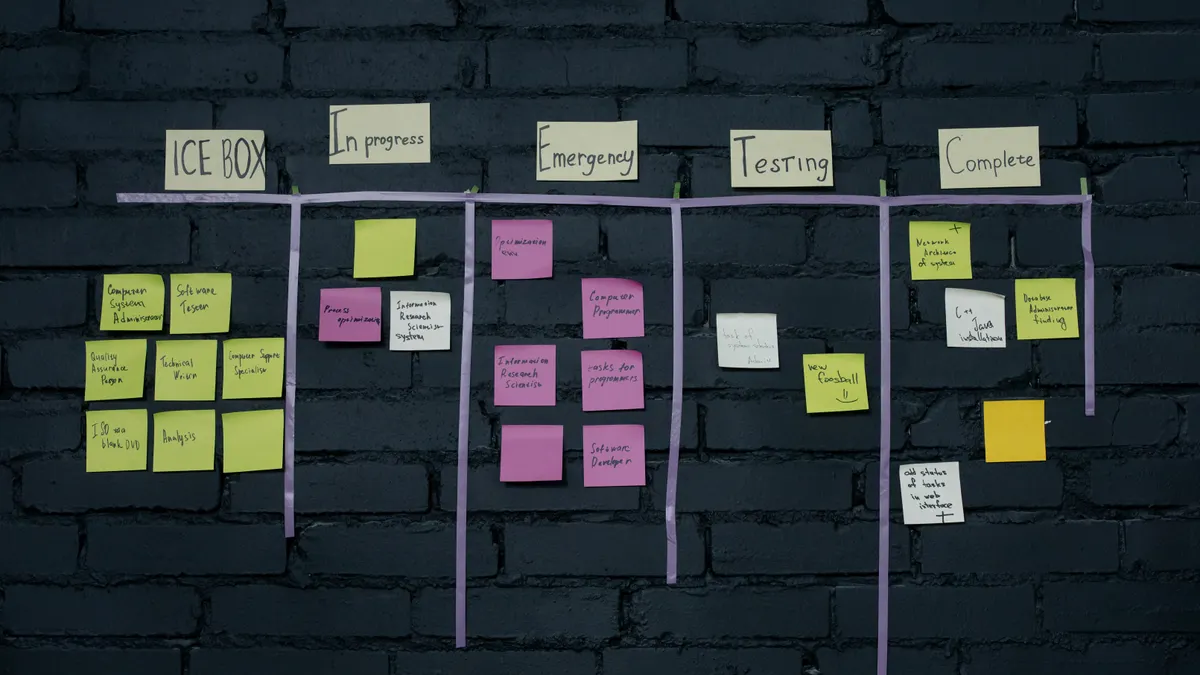
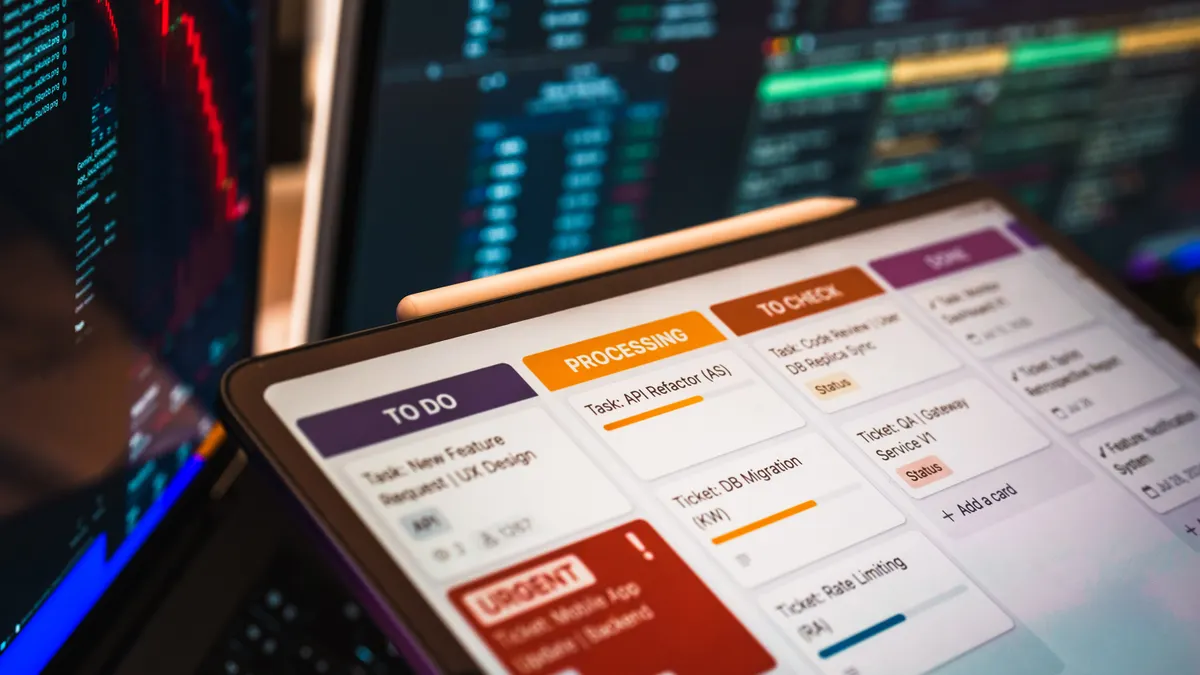
- Write down the exact path from ticket to production for one normal change, including branch creation, tests, review, merge, deploy, and verification.
- Measure the waiting time at each step in rough buckets: under 10 minutes, under 1 hour, under 1 day, over 1 day.
- Find the one step that blocks the most people most often. For many teams it is CI, review assignment, or environment setup.
- Remove manual work from that step first: cache dependencies, automate reviewer routing, or script the local bootstrap with Docker Compose, Dev Containers, or a Makefile.
- Set one standard path for most changes before creating exceptions. A “fast lane” only helps if there is a clear normal lane.
- Add one guardrail after the path is stable: branch protection, required checks, or deployment approval for the small set of high-risk services.
If onboarding is the pain, a good developer environment is worth more than a fancy deployment tool. Standardize the basics: the Node.js version, Python version, Java version, package manager, database seed, and local service dependencies. Tools like Dev Containers, Nix, Docker Compose, and asdf help when the team is losing hours to “works on my machine” drift. The point is not purity; it is reproducibility.
If CI is the pain, keep the first pipeline simple enough to finish in minutes, not an hour. Split unit tests from integration tests. Run the cheap checks on every pull request and the heavier suite on merge or on a scheduled path. Use GitHub Actions, GitLab CI, CircleCI, or Buildkite in a way that makes the feedback loop obvious. A 5-minute failure is annoying; a 45-minute failure on every small change is workflow poison.
The honest downside of fixing one bottleneck at a time is that the other problems stay visible for a while. That is still better than a broad rewrite that changes everything and improves nothing.
Quick check: if people complain most about environment setup, build times, or review delay, fix the worst one first and ignore the rest until it stops hurting.
What Should Developer Workflow and Engineering Operations Look Like Day to Day?
The best day-to-day workflow in Developer workflow and engineering operations is small, predictable, and hard to misuse. If you are trying to reduce friction for a team that ships regularly, aim for one branch, one pull request, one clear reviewer, one green check list, and one deployment path. Anything more complicated should be reserved for exceptions, not the default.
This is where many generic articles go wrong: they describe Git in theory and skip the operational details that make it tolerable in real teams. The branch strategy matters because it shapes everything else. Trunk-based development works well when changes are small and CI is reliable. Long-lived branches tend to produce integration pain and merge debt. GitFlow can help in release-heavy environments, but it often becomes overhead for product teams that deploy daily or several times a week.
A workable daily flow usually looks like this:
- Start from the current main branch, not from an old personal branch that has drifted for days.
- Make one change that fits in a reviewable pull request, ideally under a few hundred lines of diff when possible.
- Run the same local checks the CI will run, using the same package versions and environment settings.
- Open the pull request early, even before the work is perfect, if the team uses draft PRs for visibility.
- Assign the reviewer based on ownership, not whoever happens to be online.
- Merge only after required checks pass and the change has a rollback plan if it touches production behavior.
For the review part, the goal is not “more reviewers.” Two strong reviewers can still move slower than one decisive owner if the queue is messy. Set a code review SLA internally if needed, even if it is informal: same day for small changes, next business day for normal changes. Tools like CODEOWNERS in GitHub and GitLab can route reviews automatically. That matters more than people admit.
Therefore, the best workflow also keeps branch protection simple. Require passing checks, require at least one review, and protect the default branch. Do not pile on six rules because one incident scared the team. Each extra gate should solve a known failure mode.
The trade-off here is autonomy versus consistency. A highly standardized workflow makes it easier to move fast as a group, but individual engineers lose some freedom. That is fine for most teams. It is not fine for research-heavy work, one-off prototypes, or a platform team that needs to validate unusual infrastructure changes quickly.
Quick check: if your team argues more about process than code, your workflow is too vague or too complicated.
Which Engineering Operations Practices Pay Off First?
The first engineering operations practices to pay off are the ones that remove repeated interruptions, not the ones that look impressive in a tooling demo. If the team keeps losing time to access requests, broken builds, unclear ownership, or mystery alerts, focus on those before you buy a new platform.
Engineering operations sits between product work and the infrastructure that supports it. It includes environment standardization, CI/CD maintenance, observability hygiene, release coordination, incident process, and internal platform support. The best ops work is invisible when it succeeds. That is why it gets undervalued until it breaks.
A practical order of operations helps:
-
Standardize the developer workstation setup. If every engineer needs a different setup guide, the guide is already failing. Use one documented path with the same base image, language versions, and credentials flow. Tools such as Dev Containers, asdf, Homebrew bundles, or Nix can reduce drift, but only if the team agrees on one default path.
-
Stabilize CI before you automate more deployment steps. A deployment pipeline built on flaky tests creates false confidence. If a pipeline fails for reasons unrelated to code quality, developers stop trusting it. That trust gap is expensive.
-
Make ownership visible. Every service, library, and pipeline needs a name next to it. Service catalogs such as Backstage can help when the organization is big enough to lose track of ownership. A smaller team may only need a simple registry and CODEOWNERS file.
-
Clean up release mechanics. If a release still requires a “best effort” checklist in someone’s head, document it and automate the repetitive steps. Release tags, semantic versioning, changelogs, and release notes should not depend on memory.
-
Improve incident feedback. Every meaningful incident should produce one concrete workflow change, not just a postmortem document in a folder nobody reads.
The big trade-off in ops work is standardization versus local optimization. A single template for all services is easier to maintain, but some services need different deployment cadence, test coverage, or approval levels. The rule is simple: standardize the 80 percent path, not the entire world.
If you are using Kubernetes, Terraform, Argo CD, or Helm, the same logic still applies. These tools can reduce manual work, but they do not fix poor ownership or weak release discipline. A bad process in Terraform is still a bad process. A well-run one still needs review, state control, and clear change boundaries.
Quick check: if the same operational problem comes back every month, it is not an incident; it is a workflow design flaw.
What Should the Toolchain Include, and What Can You Skip?
The toolchain should include only the pieces that make the path from edit to deploy shorter, safer, or easier to understand. If a tool does not reduce waiting, reduce errors, or reduce cognitive load, it is optional. That rule saves teams from collecting software they do not need.
A sane baseline for many teams includes GitHub or GitLab for source control, a CI runner such as GitHub Actions, GitLab CI, or Buildkite, a test framework matched to the stack, and a deployment system that can roll back. On top of that, you may need package registries, secrets management, artifact storage, observability, and a ticketing system like Jira or Linear. The exact mix depends on how much you deploy and how much risk each deployment carries.
Here is the hard part: the wrong tool is often not bad, just mismatched. Jenkins can still work, but it asks for more maintenance and more configuration discipline than many teams want. GitHub Actions is convenient if your code already lives in GitHub, but very large or heavily customized pipelines can become harder to reason about. GitLab can be attractive when the team wants source control, CI, and release tools in one place. Buildkite is useful when you want more control over build agents and pipeline structure. None of these choices is universally best.
If you need to decide what to keep and what to skip, use this rule:
- Keep tools that shorten feedback loops.
- Keep tools that make ownership obvious.
- Keep tools that help a new engineer make the first successful change.
- Skip tools that duplicate a function already handled cleanly elsewhere.
- Skip dashboards nobody uses during a real incident.
A lot of teams overinvest in observability surface area and underinvest in the quality of the signals. Three well-tuned alerts, a clear runbook, and a known dashboard beat fifteen noisy ones. The same is true for test tooling. A few stable, fast tests are more useful than a huge suite that everyone distrusts.
Cost in practice is not just license price. It includes maintenance time, build minutes, local machine overhead, and the cognitive cost of switching between tools. That is why a “free” stack can still be expensive. The best choice is the one the team can operate without turning every change into a platform project.
Quick check: if a tool does not help a new engineer ship the first change faster, it probably belongs on the skip list.
How Do You Handle Releases, Incidents, and Ownership?
You handle releases, incidents, and ownership as one system, because they fail together. If a release process is unclear, incidents take longer to diagnose. If ownership is vague, rollback decisions get delayed. If incident response is unstructured, the same release mistake reappears in the next sprint.
For releases, the first question is whether you deploy continuously or on a schedule. If your team can deploy multiple times per day, keep releases boring: small batches, feature flags, clear rollback, and automated checks. If your business needs weekly or monthly release windows, then use release branches, change logs, and explicit approval steps. The wrong advice here is to pretend the two models are the same. They are not.
For incidents, a good workflow has four parts:
- Detect the issue quickly through monitoring, alerts, user reports, or deployment signals.
- Assign one incident lead who coordinates communication and one technical lead who works the problem.
- Choose the smallest safe mitigation first: rollback, disable a feature flag, scale capacity, or isolate the bad component.
- Write down the cause and one workflow change that prevents the same class of failure from repeating.
That is where engineering operations matters most. If the team cannot tell which service owns a failure, incident time balloons. If the team has no runbook, every outage becomes improvisation. If the release path is manual, recovery depends on who is awake.
A useful standard here is to make operational ownership visible next to code ownership. A service catalog, a simple on-call roster, or even a disciplined README can answer the basic question: who gets paged, who approves a rollback, and who updates the runbook? If the answer is “whoever built it,” the system is already too loose.
The honest drawback of stricter release and incident process is overhead. Engineers spend more time on coordination, documentation, and checks. That is a real cost. It is still cheaper than repeated outages, but the cost exists and should be named.
Quick check: if your release notes and incident notes live in different heads, your ownership model is too weak.
When the Standard Advice Is Wrong
The standard advice is wrong when the team is too small, too regulated, too distributed, or too specialized for a generic workflow to fit. If you are a two-person startup, a 12-person platform team, or a safety-sensitive product group, the normal “just use trunk-based development and automate everything” answer can miss the real constraint.
Here are the cases where the usual guidance breaks down:
-
Situation: A tiny team has almost no process.
What changes: The cost of ceremony is higher than the cost of mistakes.
What to do instead: Use the simplest possible workflow: one branch per change, one reviewer if available, one CI check, and a documented release step. A strict incident process with three handoffs is probably too much. -
Situation: The team ships regulated software or customer-critical financial systems.
What changes: Auditability matters as much as speed.
What to do instead: Add protected branches, change approvals, release records, and evidence retention. Consult a qualified professional for compliance-sensitive decisions, because source control alone does not solve traceability. -
Situation: The codebase is a monorepo with many services and shared libraries.
What changes: Full builds become too expensive.
What to do instead: Use path-aware CI, selective testing, and ownership boundaries. Tools like Nx, Turborepo, and Bazel can help, but only if the team is willing to maintain the structure. -
Situation: The organization is remote across several time zones.
What changes: Review latency and handoff delay grow.
What to do instead: Prefer small PRs, async review norms, clear escalation paths, and fewer meetings. A workflow that depends on “catching someone at their desk” will fail. -
Situation: The team has one or two deeply shared services with high blast radius.
What changes: Deployment risk dominates developer convenience.
What to do instead: Use canary releases, feature flags, stronger rollback mechanics, and stricter access control. The fastest workflow is not the safest one. -
Situation: CI is unstable for reasons outside the code, such as shared infrastructure flakiness.
What changes: Developers stop trusting green builds.
What to do instead: Fix the build platform before tightening review gates. More rules on top of unreliable checks only create frustration.
The standard advice fails because it assumes the same bottleneck everywhere. That is not how real teams work. A workflow that is great for a startup can be useless for a platform group, and a governance-heavy workflow can cripple a product squad that needs to move weekly.
Quick check: if your main constraint is auditability, scale, or cross-time-zone collaboration, the usual “move faster” advice is incomplete.
How Do You Know the Workflow Is Actually Working?
The workflow is working when developers spend more time changing code than waiting on the system around it. If work flows cleanly, you see shorter PR queues, fewer flaky failures, clearer ownership, and faster recovery from problems. If it is not working, the signs are usually obvious before the metrics look good.
The most useful signals are practical, not vanity metrics. Look at how long a normal change sits in draft, how often CI fails for non-code reasons, how many times developers ask where to deploy, and how often incidents repeat because the fix never became part of the workflow. If those problems are shrinking, the system is improving.
A healthy engineering operations setup also has a few visible artifacts:
- one obvious path to create a local environment
- one obvious path to run tests
- one obvious path to request review
- one obvious path to deploy
- one obvious place to find ownership and runbooks
If any of those paths require tribal knowledge, the workflow is weaker than it looks. The same is true if the team keeps adding tools without removing steps. More tooling is not the same as better operations.
The best sign of improvement is that standard work gets boring. A pull request opens, checks run, review happens, the change merges, the release goes out, and rollback exists if needed. That boring path is the point. Excitement belongs in product ideas, not in your deployment process.
The honest limit is that no workflow removes all pain. High-change systems will always have trade-offs between speed, control, and simplicity. The goal is not perfection. The goal is to make the default path predictable enough that people trust it and move through it without drama.
Quick check: if your team can describe the default path without arguing about exceptions, your workflow is probably in the right shape.
FAQ
Is trunk-based development always better than GitFlow?
No, trunk-based development is better for teams that can keep changes small, tests fast, and releases frequent. GitFlow can still fit scheduled release environments or teams with heavier release coordination. The choice depends on release frequency, risk, and how much merge overhead the team can tolerate.
Should engineering operations sit with platform engineering or with the development teams?
It should usually be shared, with platform teams owning the shared systems and product teams owning their service-specific habits. If everything sits in platform, local problems stay hidden. If everything sits with product teams, standards drift. The split depends on team size and service count.
What is the fastest way to improve CI?
Cut the pipeline into small pieces and remove the slowest unnecessary checks from the pull request path. If the test suite takes too long, split unit, integration, and end-to-end checks. If the pipeline is flaky, fix reliability before adding more steps. A 10-minute stable check is better than a 40-minute unreliable one. According to Google’s SRE work, reducing toil and stabilizing repetitive systems pays off quickly.
Do small teams need formal engineering operations?
Yes, but only the minimum that prevents repeated pain. A small team still needs clear ownership, a repeatable build, and a way to ship safely. What it does not need is a heavy approval chain or a catalog of processes nobody follows.
What is the biggest mistake teams make with developer workflow?
They optimize the tool instead of the bottleneck. A new CI platform, a new branching model, or a new deployment tool will not help if the real problem is flaky tests, unclear ownership, or review latency. The workflow should be built around the team’s actual failure mode, not a generic best practice.
Should every service have the same deployment process?
No. The default should be standardized, but high-risk services, regulated systems, and infrastructure components often need stricter checks. The mistake is applying one process to everything and then wondering why it feels slow or unsafe.
Drafted with AI; not yet reviewed by a person.